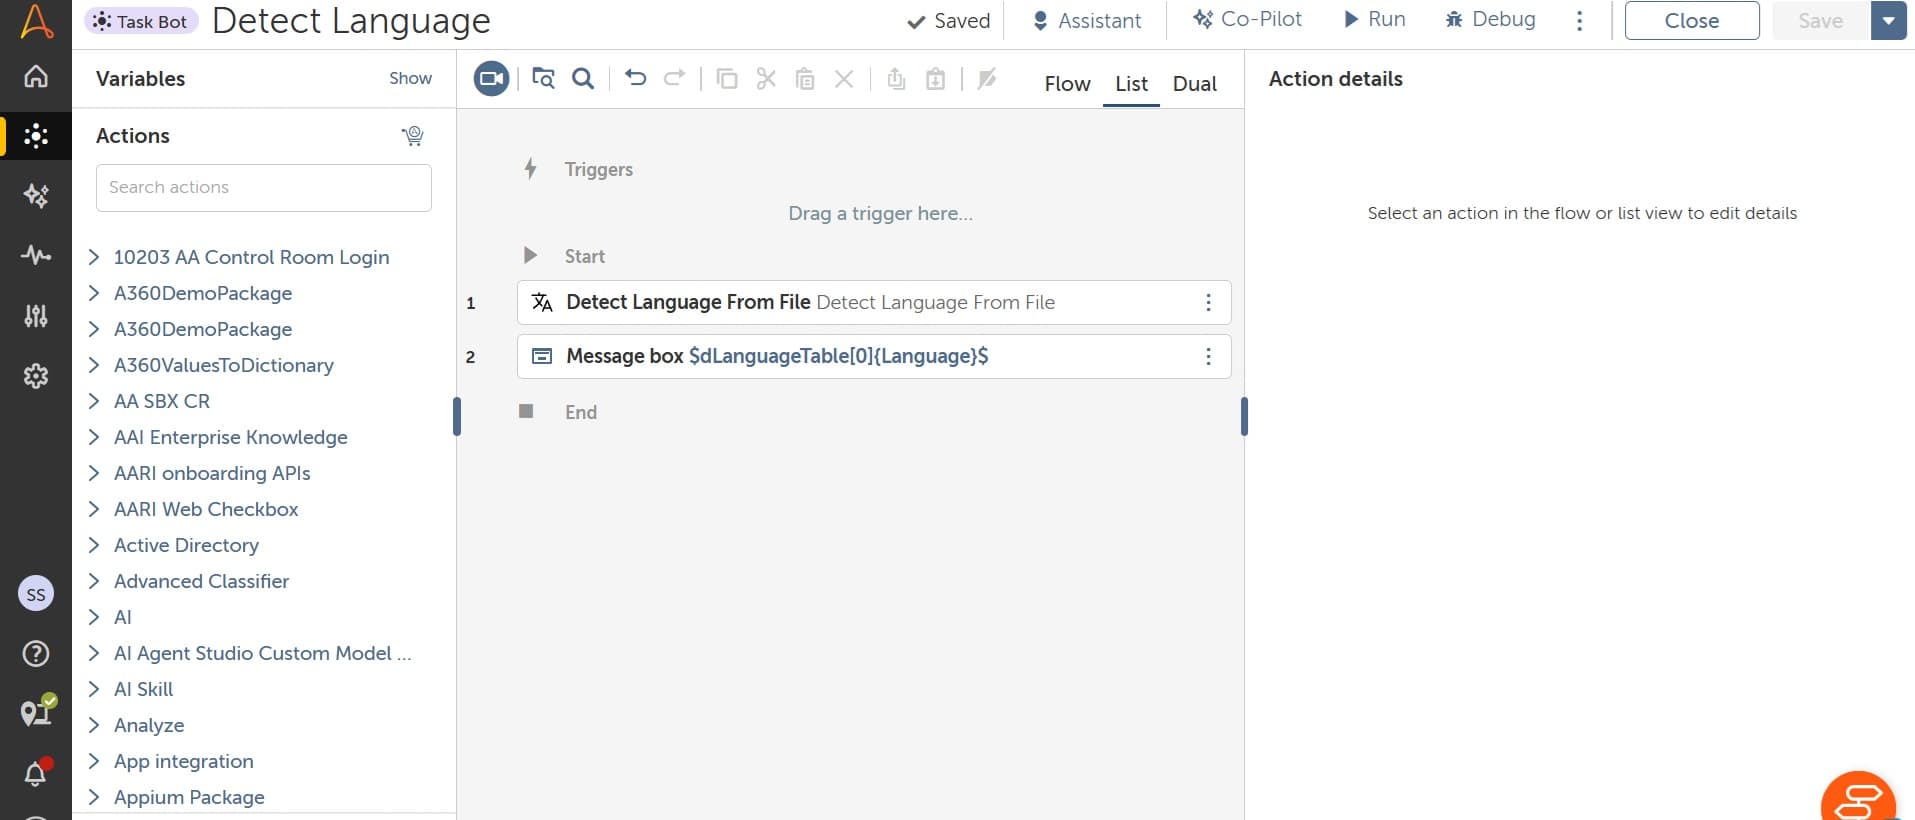
• The Language Detection package helps detect language based on the document/text passed.
• This is a Custom Package and does not require dependencies like Python/OCR setup.
• It supports digital and scanned pdfs, image files, word files and text files.
• Tesseract OCR is included along with the package and no setup is necessary to use the Bot.
• Takes in the File path as input and returns a DataTable with Detected Languages in decreasing order of confidence.
• The package will be useful as pre-processing for Document Automation when multiple instances with different languages are present. The package will help RPA decide to which instance to pass a particular document.
Features
1. 75 languages supported
2. In case of multiple language documents, the package returns a list of languages along with confidence score.
3. For single language documents the language will be value in the first row of the DataTable
4. On-Prem OCR is included as a dependency and no setup is required
5. Following extensions supported pdf, dcx, txt,png,jpg,tif,png
6. No LLM/cloud services used and data remains within the device
7. No installation or license required
8. User can choose to detect from “All Languages” or limit the number of languages to a User Provided list to improve speed and accuracy.